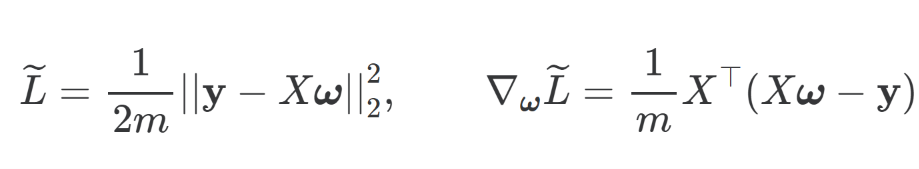
참고로 이 문서는 “Numerator Layout을 사용한다”
2022.05.08 - [.../Math] - [Math] Matrix Calculus : Numerator Layout
[Math] Matrix Calculus : Numerator Layout
원본 : [Matrix Calculus](https://souryadey.github.io/teaching/material/Matrix_Calculus.pdf)가급적 원본을 꼭 보길 권함. 1. NotationScalar는 lower case letter로 표기: $x$Vector는 lower case bold letter로 표기: $\textbf{x}=\langle x_1, x
dsaint31.tistory.com
이 문서는
최소제곱 손실함수(least-squares loss)를
parameter vector인 $\boldsymbol{\omega}$에 대해 미분하는 과정을 설명한다.
핵심은 다음과 같음:
- residual에 대한 gradient를 먼저 구한 뒤,
- chain rule을 적용하여 $\boldsymbol{\omega}$에 대한 gradient로 변환하는 것이다.
- 미분하는 동안 $X$와 $\mathbf{y}$는 상수로 취급한다.
1. 변수와 손실함수
관측치의 수를 $m$, feature의 수를 $n$이라 하면 각 변수의 dimension은 다음과 같음:
$$
X\in\mathbb{R}^{m\times n},\qquad
\boldsymbol{\omega}\in\mathbb{R}^{n\times1},\qquad
\mathbf{y}\in\mathbb{R}^{m\times1}.
$$
- 모든 vector는 column vector로 정의하며 소문자 bold로 표기한다.
- 개별 성분은 scalar이므로 일반 소문자로 표기한다.
$X\boldsymbol{\omega}$는 예측값이며,
손실함수는 실제값과 예측값의 차이를 제곱하여 평균한 scalar이다:
$$
L(\boldsymbol{\omega};X,\mathbf{y})=\frac{1}{m}||\mathbf{y}-X\boldsymbol{\omega}||_2^2.
$$
2. Residual을 도입하여 먼저 미분하기
2022.05.05 - [.../Math] - [Math] Commonly used Vector derivatives.
[Math] Commonly used Vector derivatives.
많이 사용되는 vector 도함수들을 정리함. Numeartor Layout 과 Denominator Layout을 구분하여 살펴야 함. $$f(\textbf{x})$$ $$\frac{\partial f(\textbf{x})}{\partial \textbf{x}}$$ Convention $$f(x)$$ $$\frac{df(x)}{dx}$$ $$\textbf{x}^T \t
dsaint31.tistory.com
Residual, 즉 잔차 vector를 다음과 같이 정의한다:
$$
\mathbf{r}=\mathbf{y}-X\boldsymbol{\omega}\in\mathbb{R}^{m\times1}.
$$
Vector의 squared Euclidean norm (= squared Euclidean norm) 은
자기 자신과의 inner product (내적) 이므로
loss function 를 다음과 같이 다시 쓸 수 있다.
$$
L=\frac{1}{m}\mathbf{r}^\top \mathbf{r}
=\frac{1}{m}\sum_{i=1}^{m}r_i^2.
$$
각 성분에 대해 $\partial(\mathbf{r}^\top \mathbf{r})/\partial r_i=2r_i$이므로,
이를 column vector로 모으면 다음 identity를 얻는다.
$$
\nabla_{\mathbf{r}}(\mathbf{r}^\top \mathbf{r})=2\mathbf{r},
\qquad
\nabla_{\mathbf{r}} L=\frac{2}{m}\mathbf{r}.
$$
이 결과는 $\mathbf{r}$에 대한 gradient이다.
구하려는 것은 $\boldsymbol{\omega}$에 대한 gradient이므로,
$\boldsymbol{\omega}$가 변할 때 $\mathbf{r}$이 어떻게 변하는지도 반영해야 한다.
3. Scalar chain rule에서 vector chain rule로
Scalar 변수 $u$에 대해 $v=g(u)$, $F=f(v)$라면 chain rule은 다음과 같음:
$$
\frac{dF}{du}=\frac{dF}{dv}\frac{dv}{du}.
$$
이는 입력의 변화가 중간 변수를 거쳐 최종 출력에 전달되는 정도를 각 단계의 derivative로 계산한다는 뜻이다.
현재 문제의 의존 관계도 동일하다:
$$
\boldsymbol{\omega}\longrightarrow \mathbf{r}\longrightarrow L.
$$
다만 $\mathbf{r}$에는 여러 성분이 있으므로,
하나의 parameter $\omega_j$가 각 $r_i$를 통해 손실에 미치는 영향을 모두 더해야 한다:
$$
\frac{\partial L}{\partial\omega_j}
=\sum_{i=1}^{m}
\frac{\partial L}{\partial r_i}
\frac{\partial r_i}{\partial\omega_j}.
$$
이 성분별 식을 matrix multiplication으로 정리한 것이 vector chain rule 임.
4. Jacobian과 transpose가 필요한 이유
Jacobian은 vector의 각 성분을 입력의 각 성분에 대해 미분하여 배열한 matrix이다.
(1차 미분에 해당함)
2022.05.07 - [.../Math] - [Math] Jacobian : Summary
[Math] Jacobian : Summary
이 문서는 Numerator Layout Convention을 따름.Jacobian은 vector field (or multi-variate vector-valued function)에 대한 1st order derivative에 해당함.정의input과 output이 vector인 vector function(←vector field, $\textbf{f}:\mathbb{R}^n\
dsaint31.tistory.com
여기서는 행이 residual의 성분, 열이 parameter의 성분에 대응하도록 정의한다.
$$
J=\frac{\partial \mathbf{r}}{\partial\boldsymbol{\omega}},
\qquad
J_{ij}=\frac{\partial r_i}{\partial\omega_j},
\qquad
J\in\mathbb{R}^{m\times n}.
$$
Residual을 성분으로 쓰면 다음과 같으므로 Jacobian은 $-X$이다.
$$
r_i=y_i-\sum_{k=1}^{n}X_{ik}\omega_k,
\qquad
\frac{\partial r_i}{\partial\omega_j}=-X_{ij},
\qquad J=-X.
$$
Column-gradient convention에서는 scalar 함수의 편미분들을 column vector로 모은다.
따라서 앞 절의 성분별 chain rule은 다음과 같이 표현된다.
$$
\nabla_{\boldsymbol{\omega}} L
=J^\top \nabla_{\mathbf{r}} L
=\left(\frac{\partial \mathbf{r}}{\partial\boldsymbol{\omega}}\right)^\top \nabla_{\mathbf{r}} L.
$$
Transpose된 Jacobian이 왼쪽에 오는 이유는
이 곱의 $j$번째 성분이 chain rule에서 얻은 합과 정확히 일치하기 때문임
(이는 Numerator Layout을 사용할 때 gradient를 column vector로 두는 표기 관례와도 일치함.):
$$
\bigl(J^\top \nabla_{\mathbf{r}} L\bigr)_j
=\sum_{i=1}^{m}J_{ij}\frac{\partial L}{\partial r_i}
=\frac{\partial L}{\partial\omega_j}.
$$
Dimension도 다음과 같이 일치한다:
$$
\underbrace{\nabla_{\boldsymbol{\omega}} L}_{n\times1}
=\underbrace{J^\top }_{n\times m}
\underbrace{\nabla_{\mathbf{r}} L}_{m\times1}.
$$
즉, 단순히 순서를 바꾸는 것이 아니라 성분별 chain rule을 column vector로 표현한 결과이다.
Matrix multiplication은 Scalar multiplication과 달리 피연산자들의 순서를 바꿀 수 없다.
현재 정의에서는 $J^\top $가 왼쪽에 오지만,
derivative를 row vector로 표현하면 같은 관계를 다음과 같이 쓴다:
$$
(\nabla_{\boldsymbol{\omega}} L)^\top =(\nabla_{\mathbf{r}} L)^\top J,
\qquad
(1\times n)=(1\times m)(m\times n).
$$
개인적으론
보통 곱의 순서를 외우기보다 Jacobian의 정의와 gradient의 방향을 확인하고 기재하는 걸 선호(속도는 좀 느려짐...).
5. 최종 gradient
$J=-X$와 $\nabla_{\mathbf{r}} L=(2/m)\mathbf{r}$을 chain rule에 대입한다.
$$
\begin{aligned}
\nabla_{\boldsymbol{\omega}} L
&=J^\top \nabla_{\mathbf{r}} L \\
&=(-X)^\top \left(\frac{2}{m}\mathbf{r}\right)\\
&=-\frac{2}{m}X^\top \mathbf{r}\\
&=-\frac{2}{m}X^\top (\mathbf{y}-X\boldsymbol{\omega})\\
&=\frac{2}{m}X^\top (X\boldsymbol{\omega}-\mathbf{y}).
\end{aligned}
$$
마지막 두 표현은 괄호 안의 부호를 반대로 바꾼 동일한 결과이다.
최종 gradient의 dimension은 $\boldsymbol{\omega}$와 같은 $n\times1$이다.
6. 계수 2를 상쇄하는 손실함수 convention
미분할 때 나타나는 계수 $2$를 상쇄하기 위해 손실함수를 다음과 같이 정의하기도 한다.
$$
\widetilde L=\frac{1}{2m}||\mathbf{y}-X\boldsymbol{\omega}||_2^2,
\qquad
\nabla_{\boldsymbol{\omega}}\widetilde L
=\frac{1}{m}X^\top (X\boldsymbol{\omega}-\mathbf{y}).
$$
이 정의는 원래 손실함수를 $1/2$배 한 것이므로
최소화하는 $\boldsymbol{\omega}$는 같고
gradient의 크기는 절반이다.
7. parameter가 scalar 인 경우 : $n=1$
만약 $\omega$가 scalar라면
$$ \nabla_{\omega}\widetilde L =\frac{d\widetilde L}{d\omega}.$$
예를 들어 $\mathbf{x},\mathbf{y}\in\mathbb{R}^{m}$이고
$$\widetilde L(\omega) =\frac{1}{2m}\|\mathbf{y}-\mathbf{x}\omega\|_2^2$$
이면,
$$ \nabla_{\omega}\widetilde L =\frac{1}{m}\mathbf{x}^\top (\mathbf{x}\omega-\mathbf{y}) \in\mathbb{R}. $$
곱의 dimension은 \((1\times m)(m\times1)=1\times1\)이며 따라서 row와 column의 구분도 사라짐: scalar.
$\omega$가 scalar일 때, $x_i,y_i$로 쓰면 다음과 같음:
$$ \widetilde L(\omega) =\frac{1}{2m}\sum_{i=1}^{m}(y_i-x_i\omega)^2. $$
Chain rule을 적용하면
$$ \begin{aligned} \nabla_{\omega}\widetilde L =\frac{d\widetilde L}{d\omega} &=\frac{1}{2m}\sum_{i=1}^{m} 2(y_i-x_i\omega)(-x_i)\\ &=-\frac{1}{m}\sum_{i=1}^{m}x_i(y_i-x_i\omega)\\ &=\frac{1}{m}\sum_{i=1}^{m}x_i(x_i\omega-y_i). \end{aligned} $$
여기서 $x_i,y_i,\omega$는 모두 scalar이므로, 결과도 scalar가 됨.
참고로 이 gradient와 perceptron의 update를 비교해봐도 좋은 공부가 됨.
같이보면 좋은 자료들
2023.10.19 - [Programming] - [ML] Gradient Descent Method: 경사하강법
[ML] Gradient Descent Method: 경사하강법
Gradient Descent Method (경사하강법) : 1. 정의 및 수식Steepest Gradient Descent Method로도 불리는Gradient Descent Method(경사하강법)는 여러 Optimization 방법 중 가장 많이 사용되는 방법들 중 하나임.training set $X$
dsaint31.tistory.com
2023.06.24 - [.../Math] - [Math] Gradient (구배, 기울기, 경사, 경도) Vector
[Math] Gradient (구배, 기울기, 경사, 경도) Vector
Gradient (구배, 기울기, 경사, 경도), $\nabla f(\textbf{x})$Multi-Variate Function (=Scalar Field, Multi-Variable Function) $f(\textbf{x})$에서 input $\textbf{x}$의 미세한 변화에 대해 (scalar) output이 1) 가장 가파르게 증가하
dsaint31.tistory.com
https://dsaint31.me/mkdocs_site/ML/ch08/dl_perceptron_vs_lr/#sgd-linear-regression
BME
Linear Models Linear Regression Logistic Regression Machine Learning Perceptron SGD SGDClassifier Perceptron과 Linear Regression, Logistic Regression 의 차이 Perceptron, Logistic Regression과 Linear Regression은 모두 linear combination을 사용함
dsaint31.me
'Programming > ML' 카테고리의 다른 글
| SwiGLU (Swish-Gated Linear Unit) (0) | 2026.09.19 |
|---|---|
| Forward-Mode Automatic Differentiation (0) | 2026.09.02 |
| Empirical risk (0) | 2026.08.12 |
| Monte Carlo와 MCMC (0) | 2026.08.02 |
| DropPath 와 Stochastic Depth (0) | 2026.07.10 |